AI Automated Data Insight Pipeline
End-to-End Automated Data Profiling, Context-Aware Title Synthesis, NLP Sentiment Detection, and Executive Report Generation
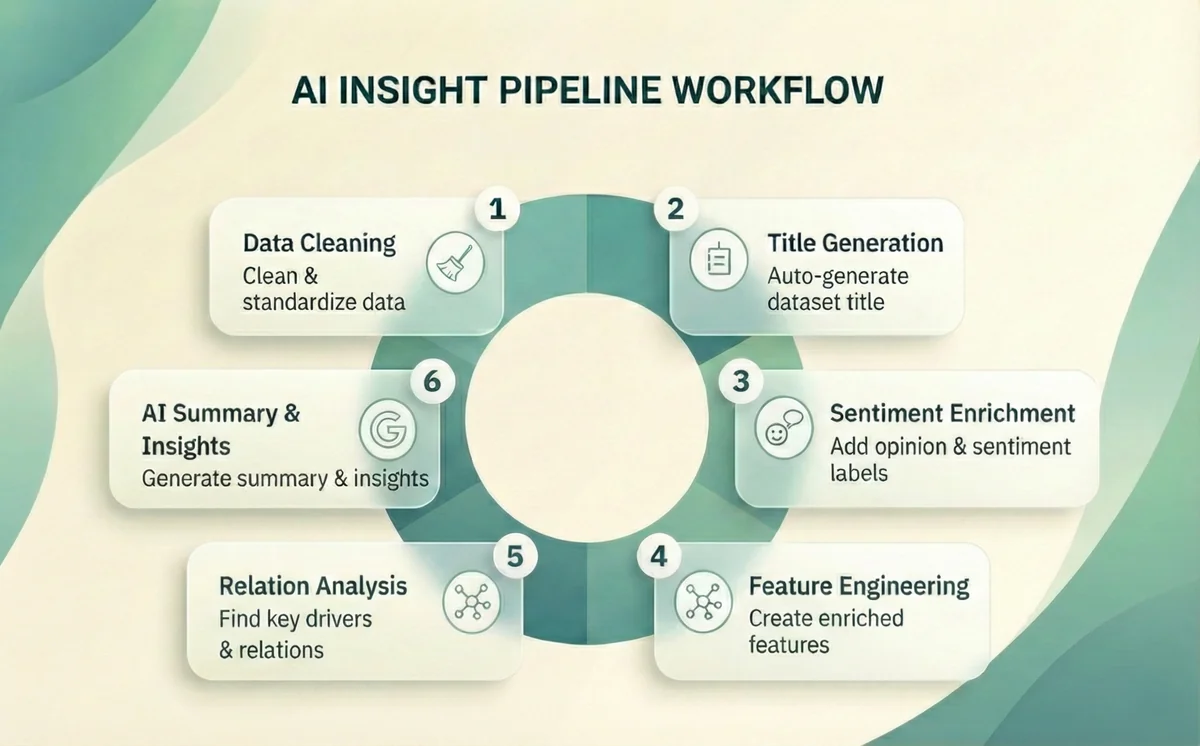
System Context & Value Proposition
The AI Insight Pipeline is an automated intelligence pipeline engineered to eliminate repetitive exploratory data analysis (EDA). Given any raw CSV or JSON dataset, the pipeline autonomously executes data profiling, generates context-aware dataset titles via a fine-tuned GPT-2 model, performs data sanitization, executes deep sentiment analysis on text fields, engineers numerical and categorical features, calculates relationship correlation matrices, and generates an executive HTML/PDF analytical report.
Data scientists and business analysts expend up to 70% of initial project hours writing boilerplate scripts for profiling, cleaning missing entries, and computing correlations.
System Architecture & Execution Flow
Raw Dataset (CSV / JSON)
      ↓
[Step 1: CSV Profiling] (Types, Missing %, Skewness, Outliers)
      ↓
[Step 2: Title Synthesis] (Fine-Tuned GPT-2 Generates Context Title)
      ↓
[Step 3: Clean & Validate] (Imputation, Type Normalization, Outlier Clamping)
      ↓
[Step 4: Sentiment Analysis] (Existing Column vs RoBERTa Transformer Inference)
      ↓
[Step 5: Feature Engineering] (Standard Scaling, Log Transforms, One-Hot Encoding)
      ↓
[Step 6: Relation Discovery] (Pearson / Spearman Correlations & VIF Matrices)
      ↓
[Step 7: Insight Synthesis] (Gemini LLM Generates Executive Summary)
      ↓
[Step 8: Report Synthesizer] (Interactive HTML & PDF Dashboard)
Multi-Tier Architectural Layers
Pandas, NumPy, SciPy
Automated schema inference, missing value distribution computation, interquartile range (IQR) outlier detection, and statistical skewness evaluation.
HuggingFace GPT-2
Fine-tuned sequence generator that inspects sample rows and column headers to formulate an accurate descriptive dataset title.
PyTorch, RoBERTa / Transformers
Identifies textual columns dynamically and executes batched sentiment classification into Positive, Neutral, and Negative polarity distributions.
Gemini API, Jinja2, Matplotlib
Synthesizes correlation matrices into natural language findings and renders standalone HTML reports with embedded SVG charts.
Core Engineering Modules & Workflows
Computes datatype identification, null value percentages, cardinality, kurtosis, and statistical quartile summaries across all columns.
Fine-tuned GPT-2 generative transformer formulates descriptive business titles based on raw tabular structures.
Imputes missing numerical values via median strategies, normalizes datetime formats, and clips extreme statistical anomalies.
Runs transformer tokenizers on text columns to generate sentiment distributions with probability confidence intervals.
Applies log-transforms on skewed distributions, one-hot encodes categorical fields, and scales numerical features.
Calculates Pearson and Spearman correlation matrices with automated Variance Inflation Factor (VIF) collinearity alerts.
Generates polished HTML and printable PDF dashboards featuring embedded distribution histograms, correlation heatmaps, and LLM-written summaries.
Persistence Schemas & Execution Contracts
Database Schema & Entity Structure
Pipeline Ingestion Schema:
  Input: { file_path: "dataset.csv", target_col?: "sentiment", output_format: "html" | "pdf" }
  Output Metrics Object:
    ├── profile: { rows: int, cols: int, missing_cells: int, memory_mb: float }
    ├── sentiment_summary: { positive: float, neutral: float, negative: float }
    ├── correlations: { top_positive: Array<{col1, col2, score}>, top_negative: Array }
    └── executive_summary: string (LLM-synthesized analytical findings)
Key Endpoints & Query Interfaces
Engineering Challenges & Specifications
Technical Obstacles Solved
Resolution: Designed heuristic type-detection algorithms analyzing string patterns, datetime formats, and uniqueness ratios to infer column roles automatically.
Resolution: Implemented batched tokenization and FP16 inference in PyTorch to prevent CUDA out-of-memory errors on commodity hardware.
Technology Stack Matrix
| Category | Tooling & Frameworks |
|---|---|
| Language | Python 3.10+ |
| Data Manipulation | Pandas, NumPy, SciPy |
| Deep Learning Framework | PyTorch 2.x |
| NLP Transformers | HuggingFace (GPT-2, RoBERTa) |
| Generative Insights | Google Gemini API |
| Visualization | Matplotlib, Seaborn, Jinja2 Templates |